Marketing analytics
that checks its own work.
Echelonify measures what every channel and every prescriber contributes, recommends the budget, and proves the answer before anyone reads it.
Channels
Plans
Runs
Last night's refresh
- Checking… no duplicate rows at declared grain
- At least 4 periods of history
- Outcome has no nulls
- Model fit above the floor
- Holdout error under 25%
- Signs match expectations
- Contributions reconcile
Echelonify agent
Answers from the run record
Morning, Aarav
I want to know what is driving prescribing this quarter
Decide
Trust
Move the money
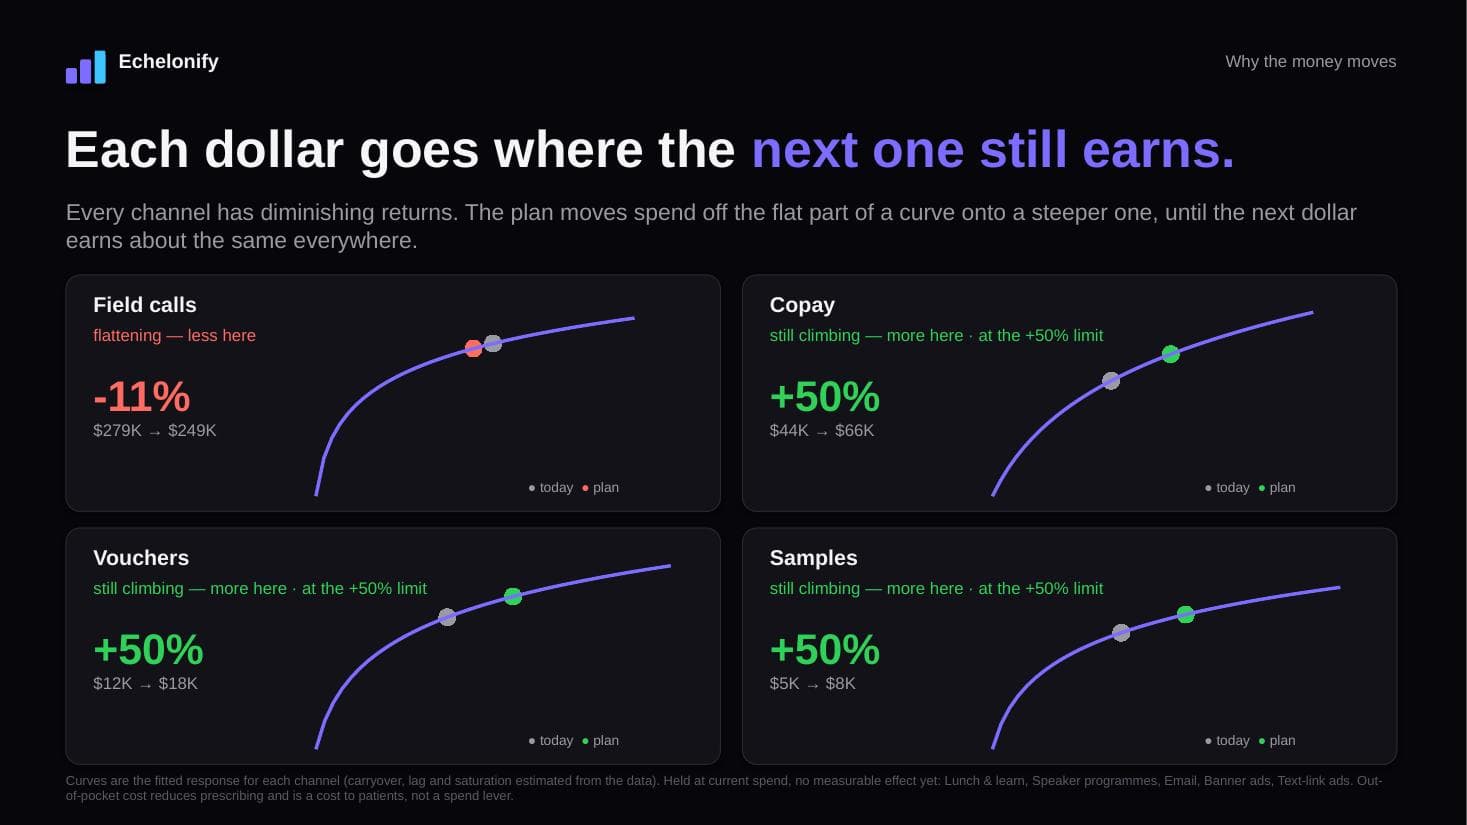
Same budget. The plan moves spend to where the next dollar still earns.
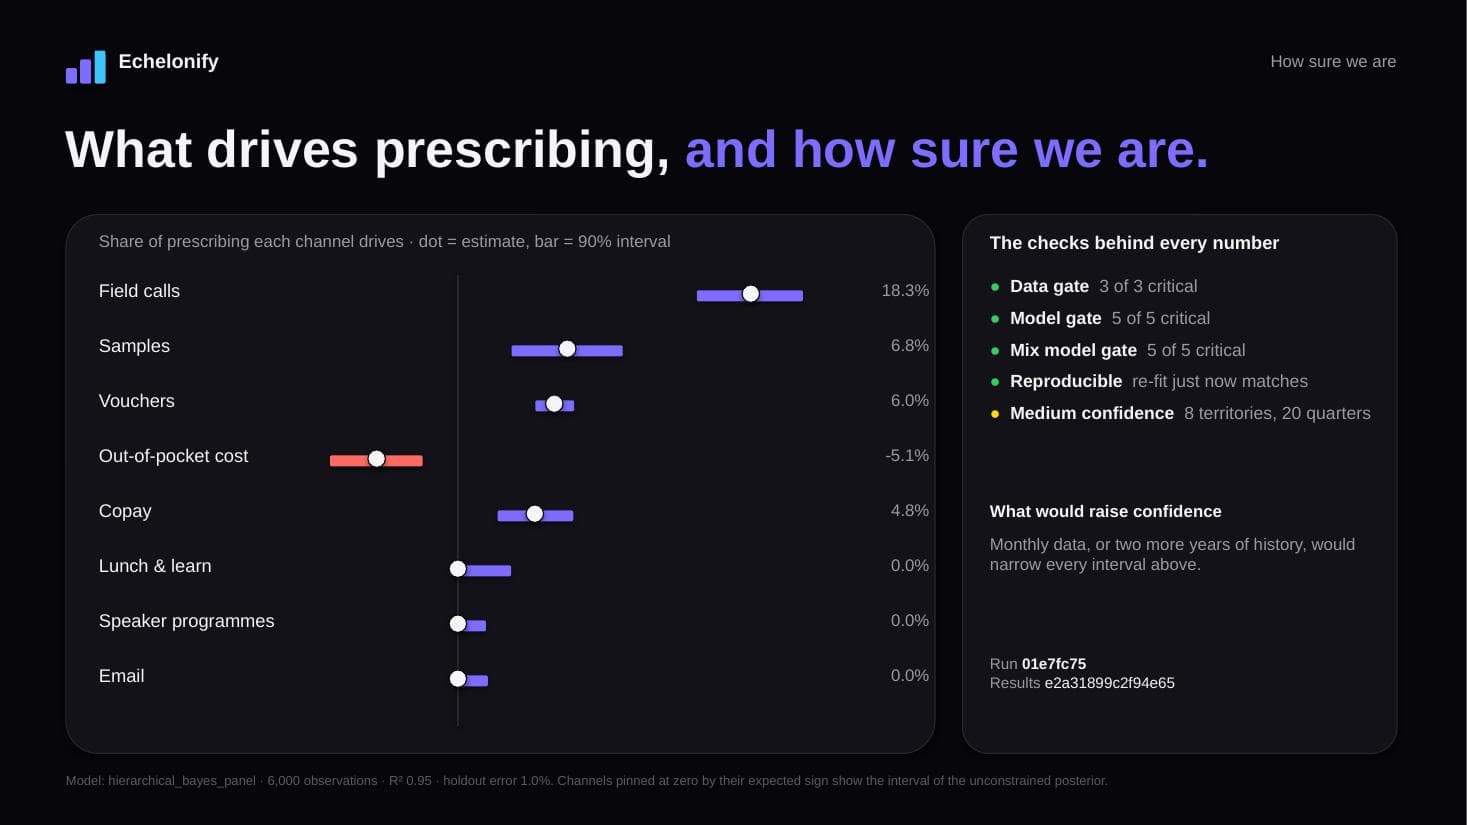
Every estimate carries a 90% interval from a hierarchical Bayesian model fitted on the prescriber × period panel.
One run, checked at every step.
Scroll through last night's refresh. At each step the platform writes its record, then a gate decides whether it may continue. Code passes most gates. One needs a named person.
Data lands, and is checked before anyone reads it
- Syncs overnight from Snowflake, Databricks or Azure
- Grain, history, completeness and sparsity checked
- A critical failure stops the run here
Trust that runs with the numbers,
not after them.
Every step is checked, approved and recorded as it happens, so the evidence your brand, finance and compliance teams need already exists when they ask for it.
Checks decided by code
Whether a run may continue is decided against thresholds you set. No model decides a pass.
Named approvals
Only a director can approve a plan, and the name comes from their Microsoft Entra sign-in, not the request.
Uncertainty on every number
Every contribution and return carries a 90% interval; low-power results are labelled as such.
Reproducible on demand
Each run records its inputs, settings and a hash of every step. Reproduce re-fits it and compares.
An agent that can't move money
The agent answers from the run record and explores scenarios. It cannot save, approve or change thresholds.
Your cloud, your data
Deploys into your Azure subscription. Models run on your Azure OpenAI deployment.
| Time | Who | Action |
|---|---|---|
| 09:41 | Field Director | plan.approved |
| 09:40 | Code | run.reproduced |
| 09:22 | Agent | question.answered |
| 09:15 | Brand lead | plan.saved |
| 08:58 | Analytics | divergence.reviewed |
| 02:07 | Code | manifest.closed |
| 02:06 | Code | mix_gate.passed |
| 02:06 | Code | mix_model.fitted |
| 02:05 | Code | model_gate.passed |
| 02:04 | Code | data_gate.passed |
| 02:00 | Scheduler | run.started |
Not just which channel.
Which doctors.
A prescriber-level engine decides who to target and whether the effect is causal. A mix model decides how much each channel gets. Its causal estimates become the mix model's priors, and the two are compared on every run.
The HCP engine
Who to target
Driver importance, then difference-in-differences, double ML, propensity matching and an X-learner on the prescriber panel, reported by territory.
The mix model
How much, and where
Hierarchical Bayesian model on the prescriber × period panel, pooled across territories, with a 90% interval on every channel.
Where they disagree, you see it. Neither is ever quietly overridden.
Defend the budget
in one slide.
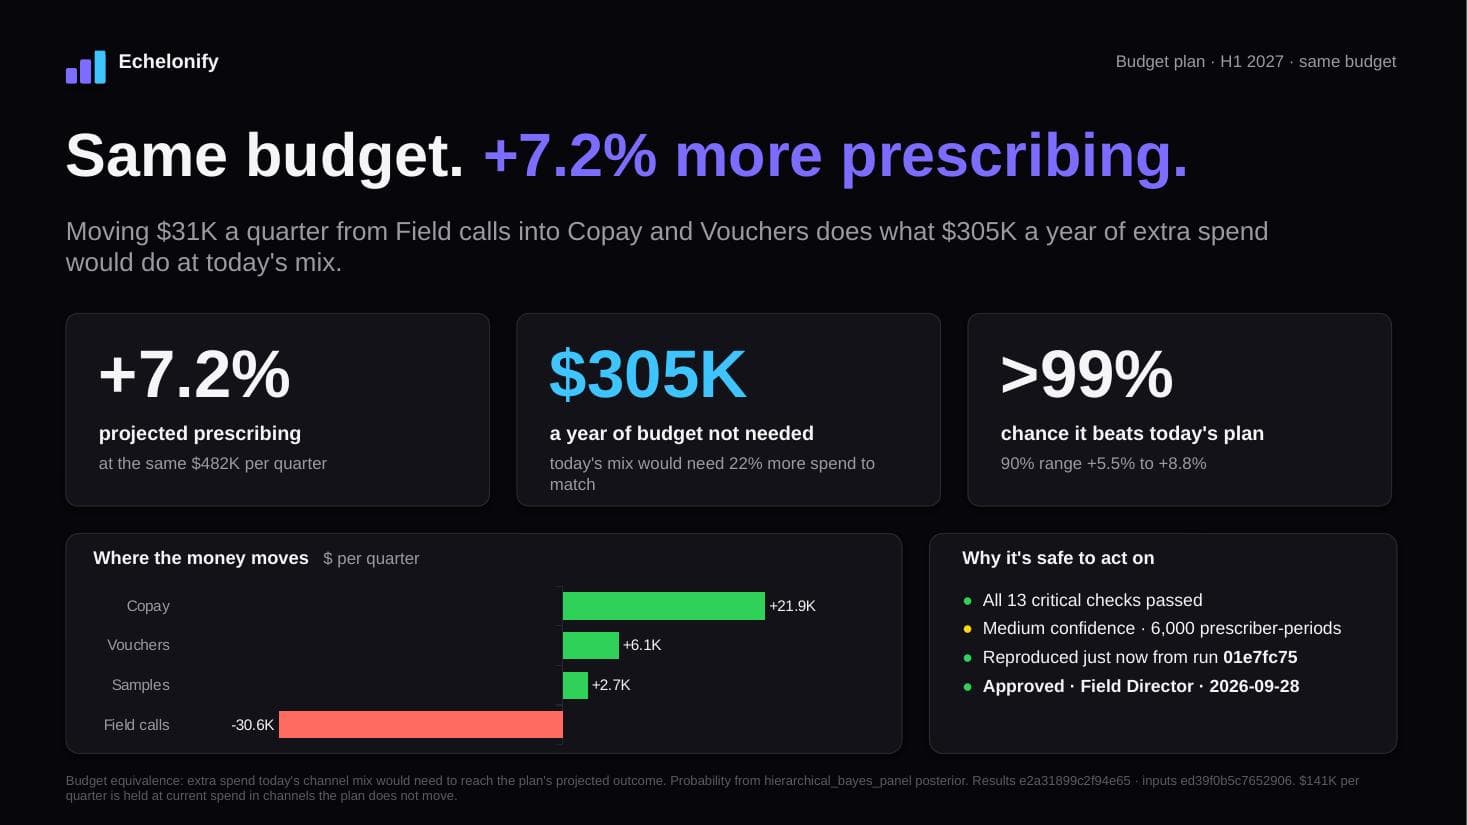
Every approved plan exports as a board-ready slide, generated from the run itself: what it's worth, where the money moves, how sure we are, and who approved it.
- What it's worth. Today's mix would need 22% more budget to match the plan.
- How sure. A better than 99% chance it beats today's allocation, with the range.
- Why it's safe. Every check that passed, and a reproducibility test run as the slide is made.
See your own numbers.
Two of your datasets. Six weeks. Nothing moves until you say so.
- Week 1
Deploy into your Azure subscription, behind your Microsoft Entra sign-in.
- Weeks 2–4
Run on two of your datasets. Backtest against your current model and real holdout quarters.
- Weeks 5–6
Build a plan with your brand team, and take the slide to your budget review.
What pharma teams ask
before a pilot
It measures what each channel and each group of prescribers contributes to prescribing, recommends how to allocate the next budget, and checks its own work before anyone reads the result. A person approves anything that moves money.